> For the complete documentation index, see [llms.txt](https://hitchhikerguide.gitbook.io/reinforcement-learning/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://hitchhikerguide.gitbook.io/reinforcement-learning/model-free-learning-estimate-the-value-function-of-an-unknown-mdp.md).

# Model free Learning - Estimate the value function of an unknown MDP

Topics:&#x20;

1. Monte Carlo
2. Temporal-Difference Learning
3. TD(lamda)

\
Assumptions:

* Policy is given
* Dynamics of the environment (transition probability and reward function is unknown)

\
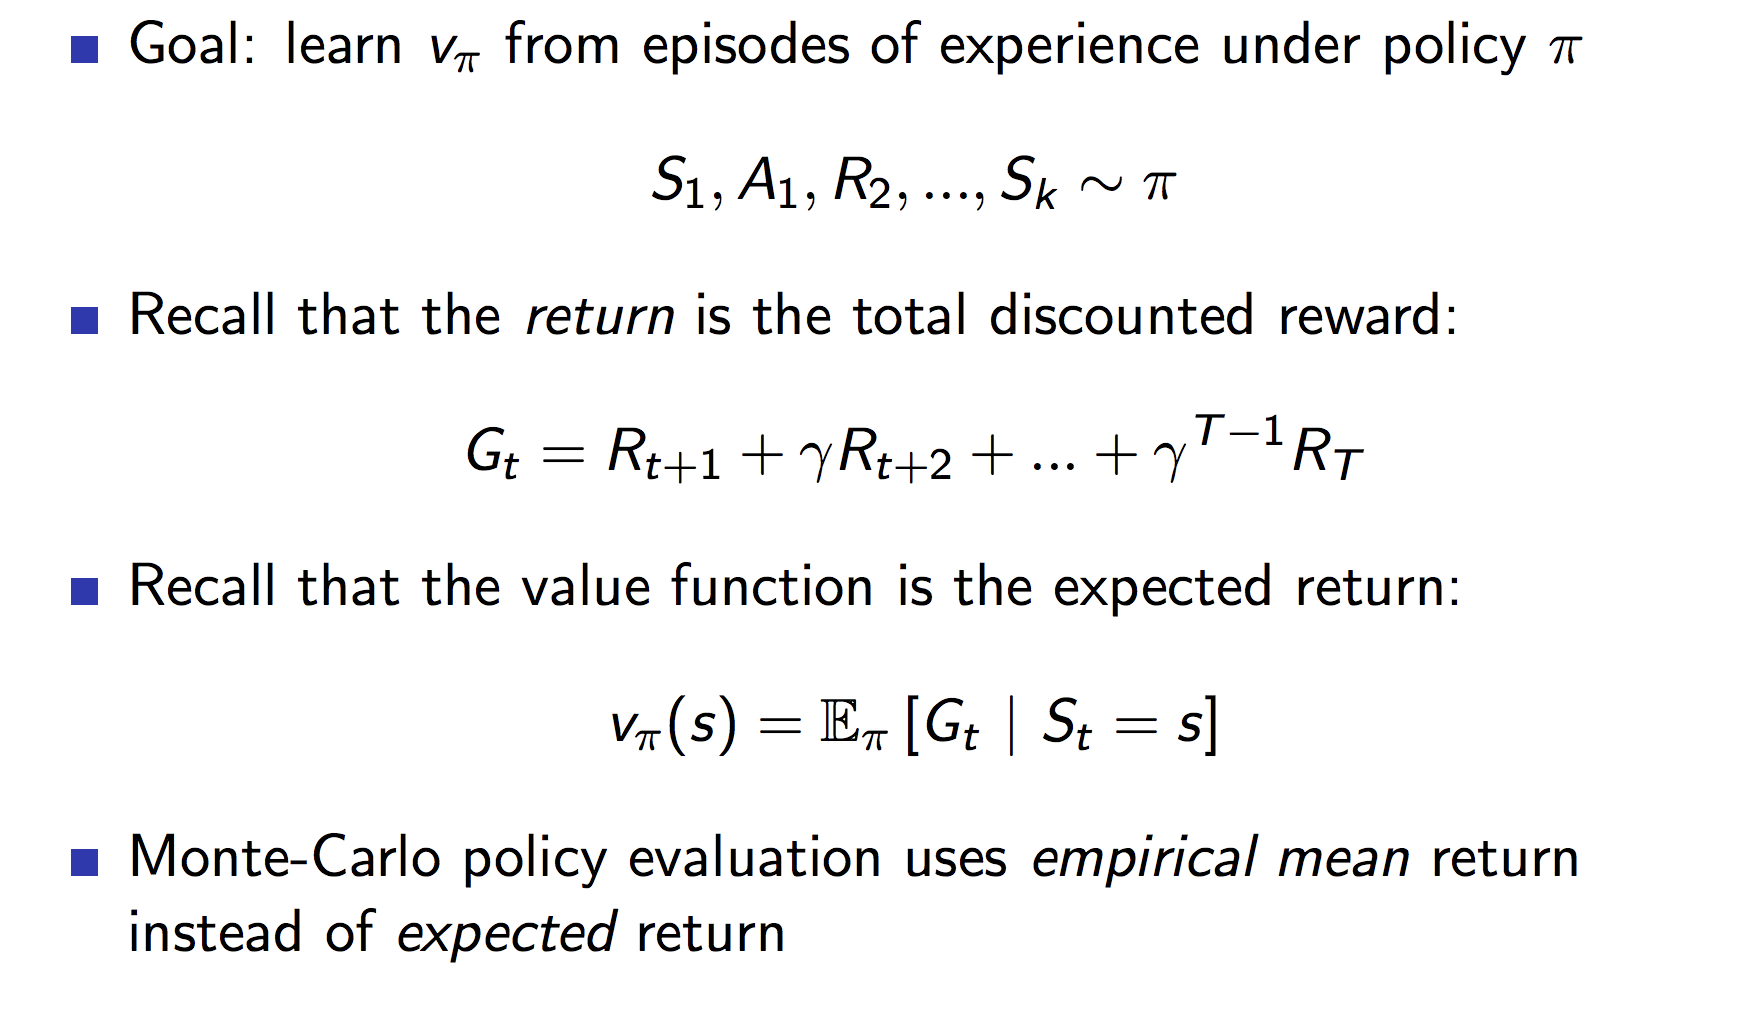
Goal is find out how good are the states under policy pi. (EVALUATION)\
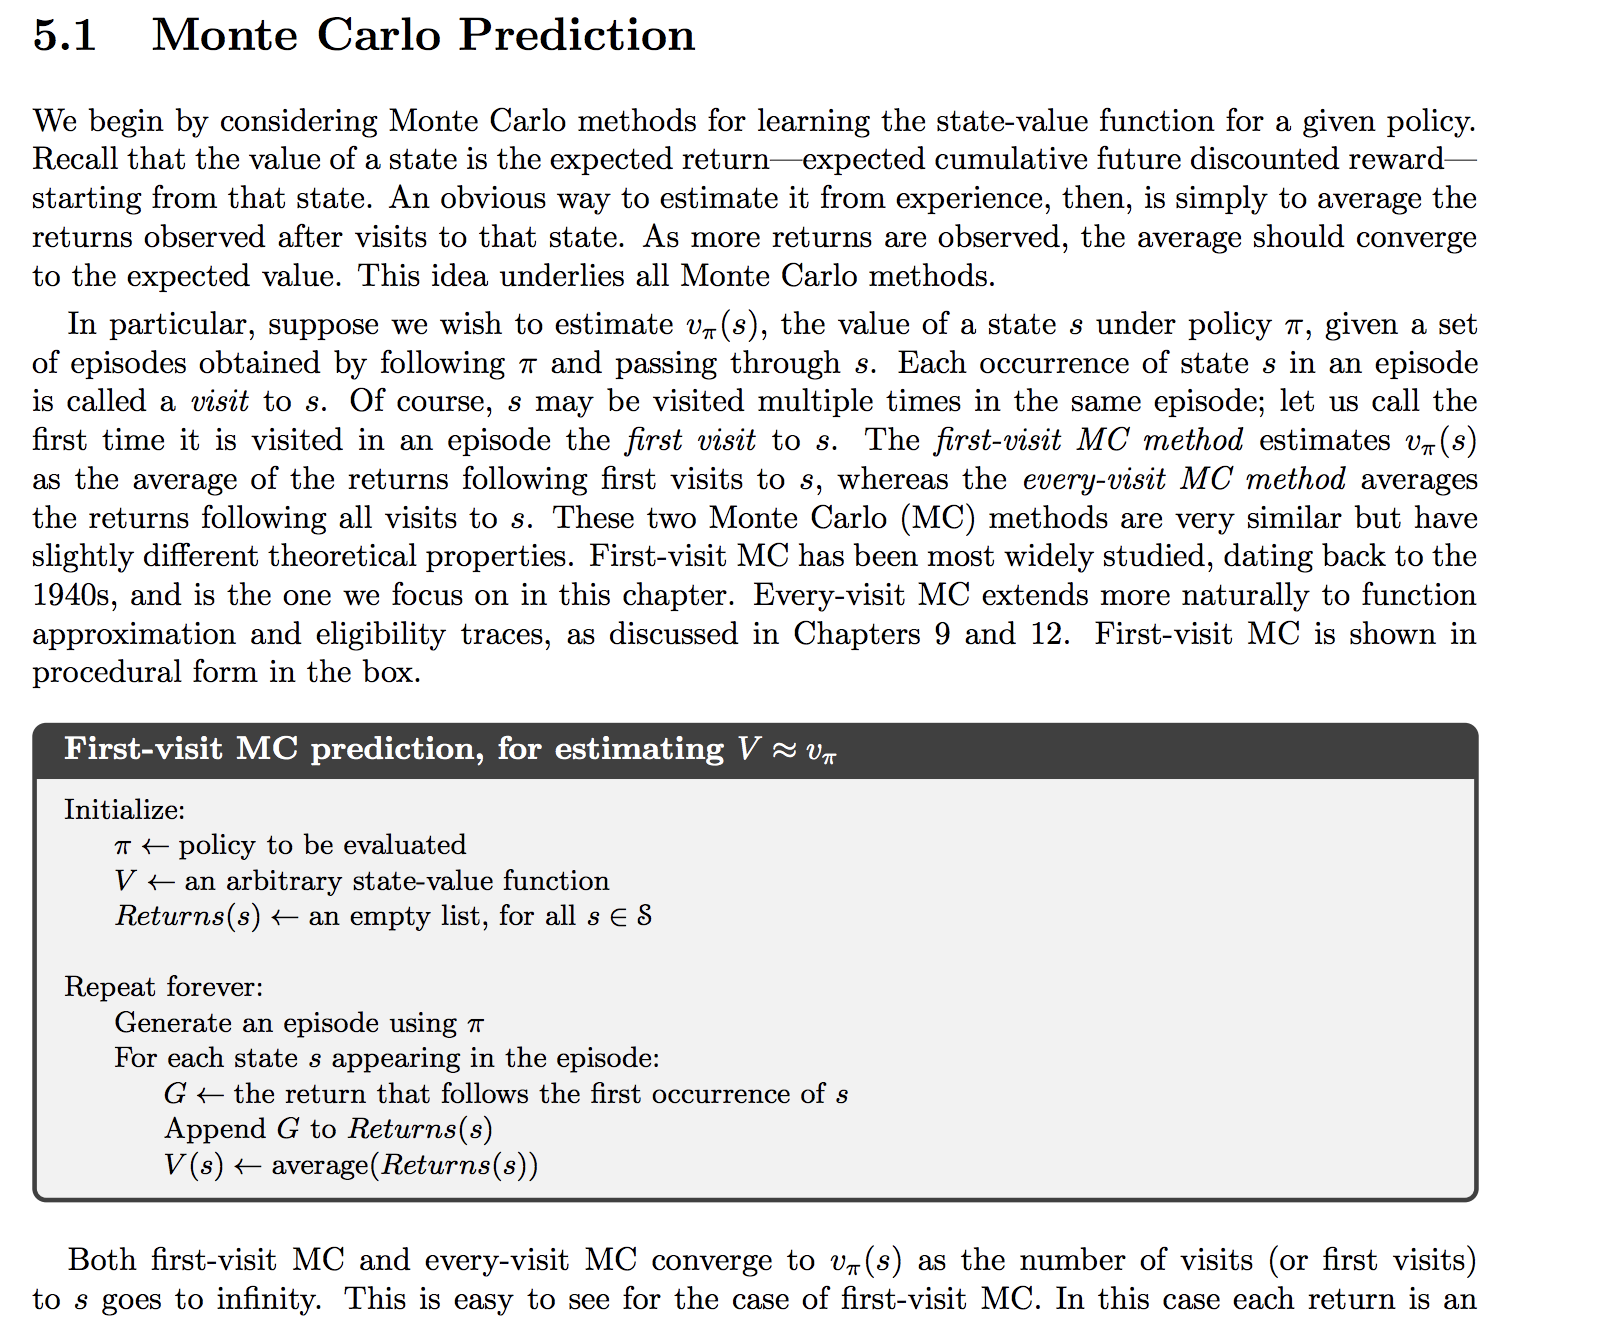
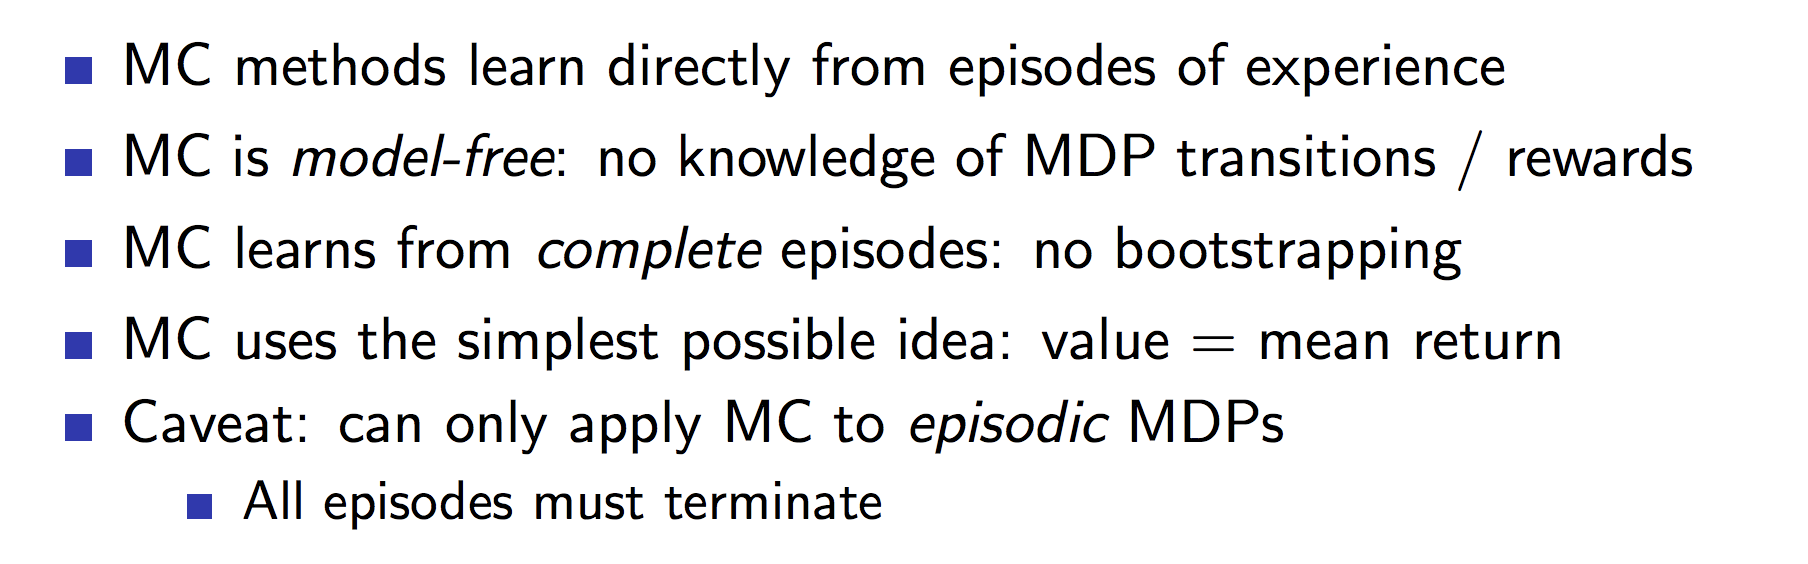
Monte Carlo methods are ways of solving the reinforcement learning problem based on averaging sample returns

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539678694961_Screen+Shot+2018-10-16+at+7.30.50+pm.png" alt=""><figcaption></figcaption></figure>

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539678998691_Screen+Shot+2018-10-16+at+7.36.28+pm.png" alt=""><figcaption></figcaption></figure>

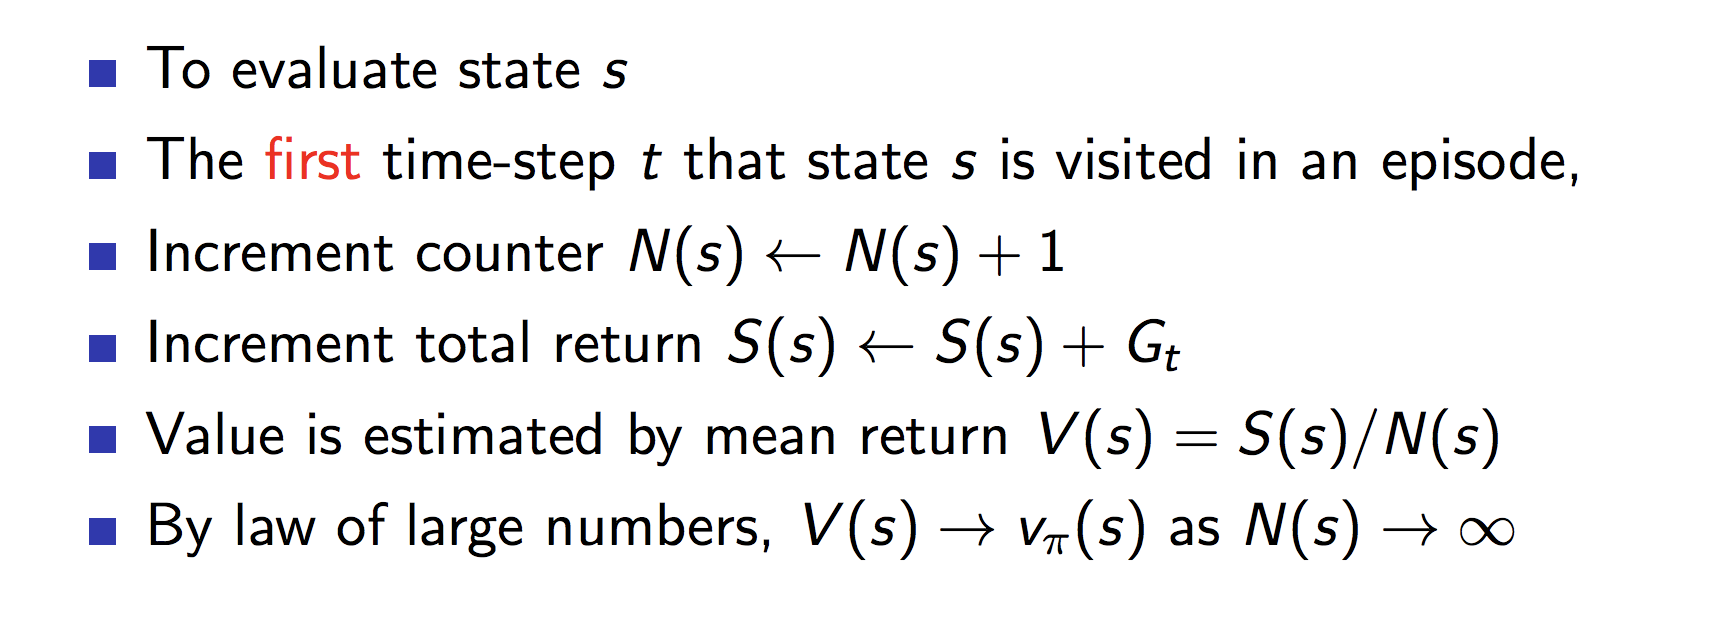
<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539679072547_Screen+Shot+2018-10-16+at+7.37.21+pm.png" alt=""><figcaption><p>You only increment the counter once in each Episode - In Every time step you can keep on incrementing it</p></figcaption></figure>

<br>

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539677791004_Screen+Shot+2018-10-16+at+7.16.08+pm.png" alt=""><figcaption></figcaption></figure>

\ <br>

### Temporal-Difference Learning

\
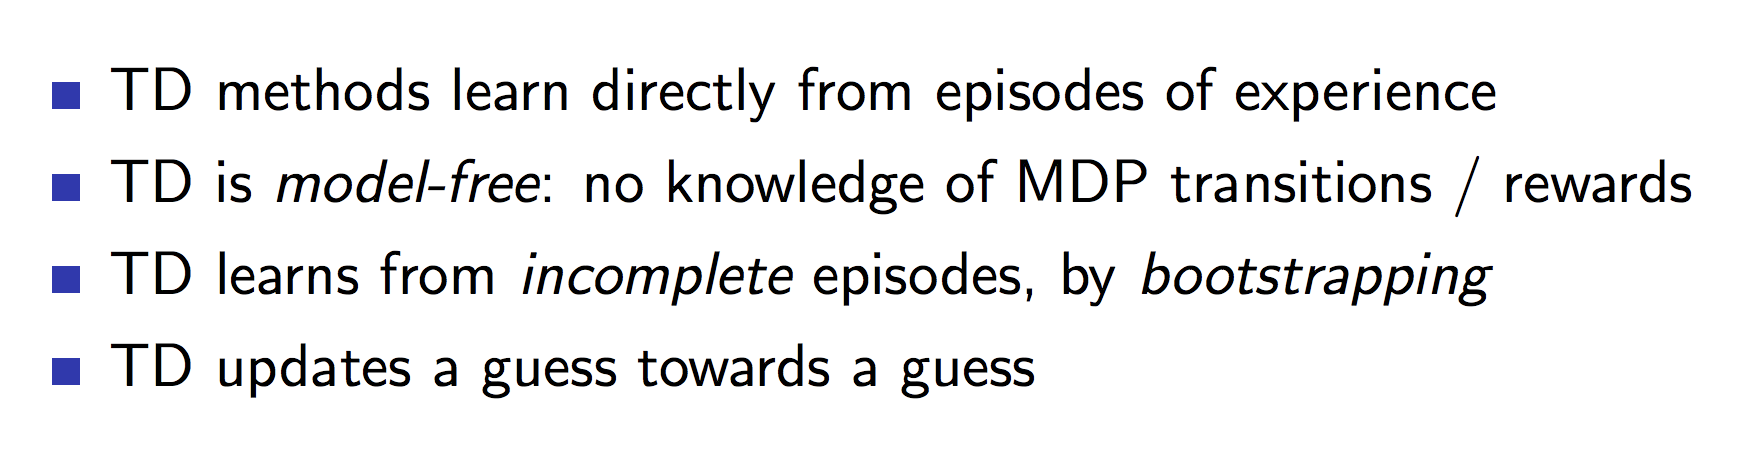
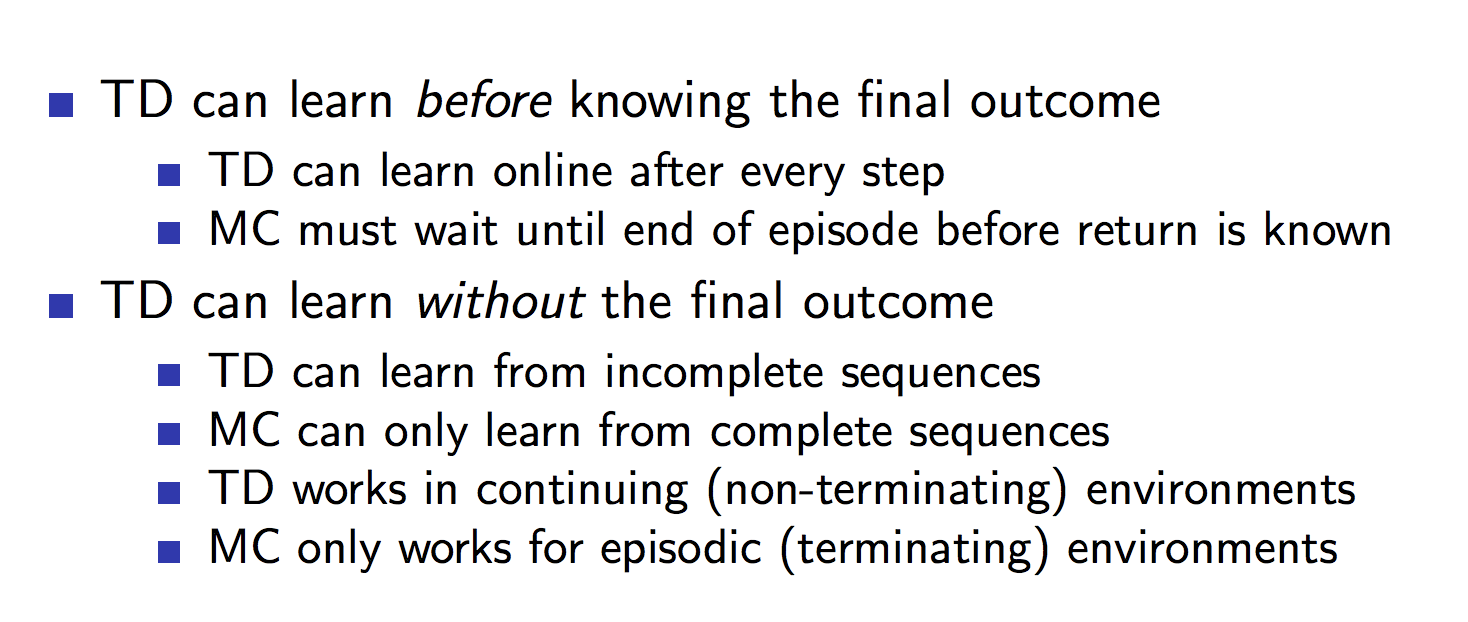
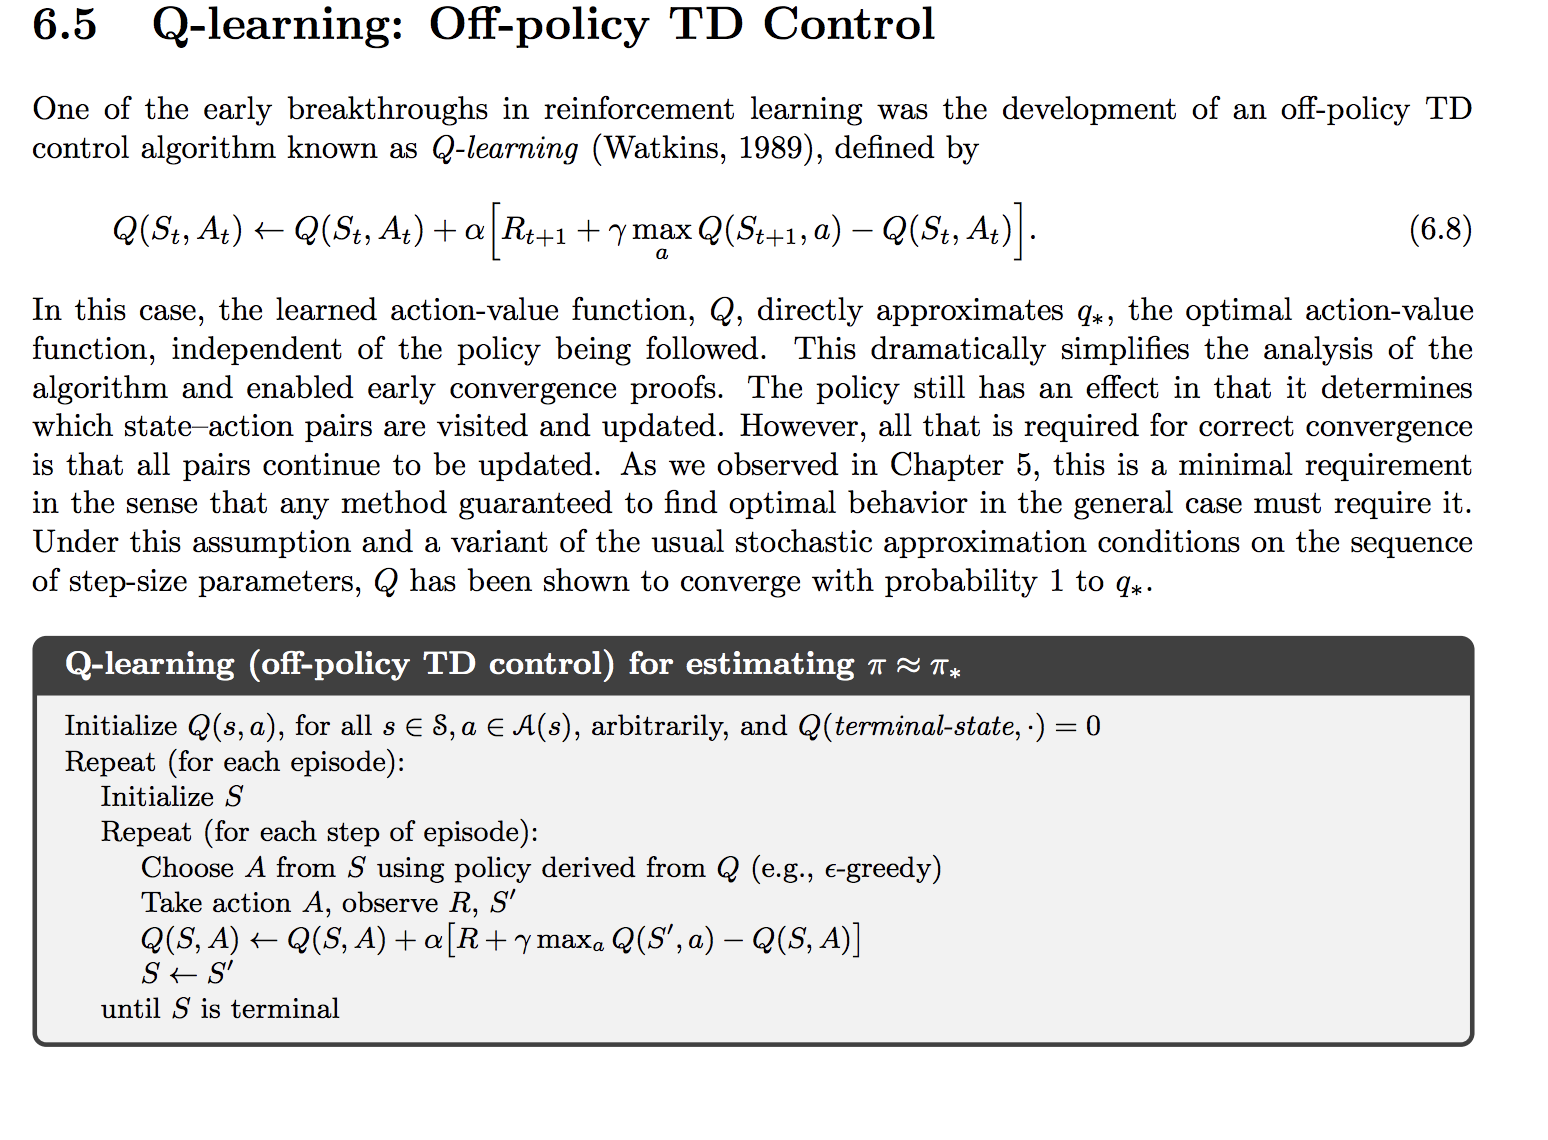
If one had to identify one idea as central and novel to reinforcement learning, it would undoubtedly be temporal-difference (TD) learning. TD learning is a combination of Monte Carlo ideas and dynamic programming (DP) ideas. Like Monte Carlo methods, TD methods can learn directly from raw experience without a model of the environment’s dynamics. Like DP, TD methods update estimates based in part on other learned estimates, without waiting for a final outcome (they bootstrap). The relationship between TD, DP, and Monte Carlo methods is a recurring theme in the theory of reinforcement learning\
\ <br>

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539684515608_Screen+Shot+2018-10-16+at+9.08.17+pm.png" alt=""><figcaption></figcaption></figure>

<br>

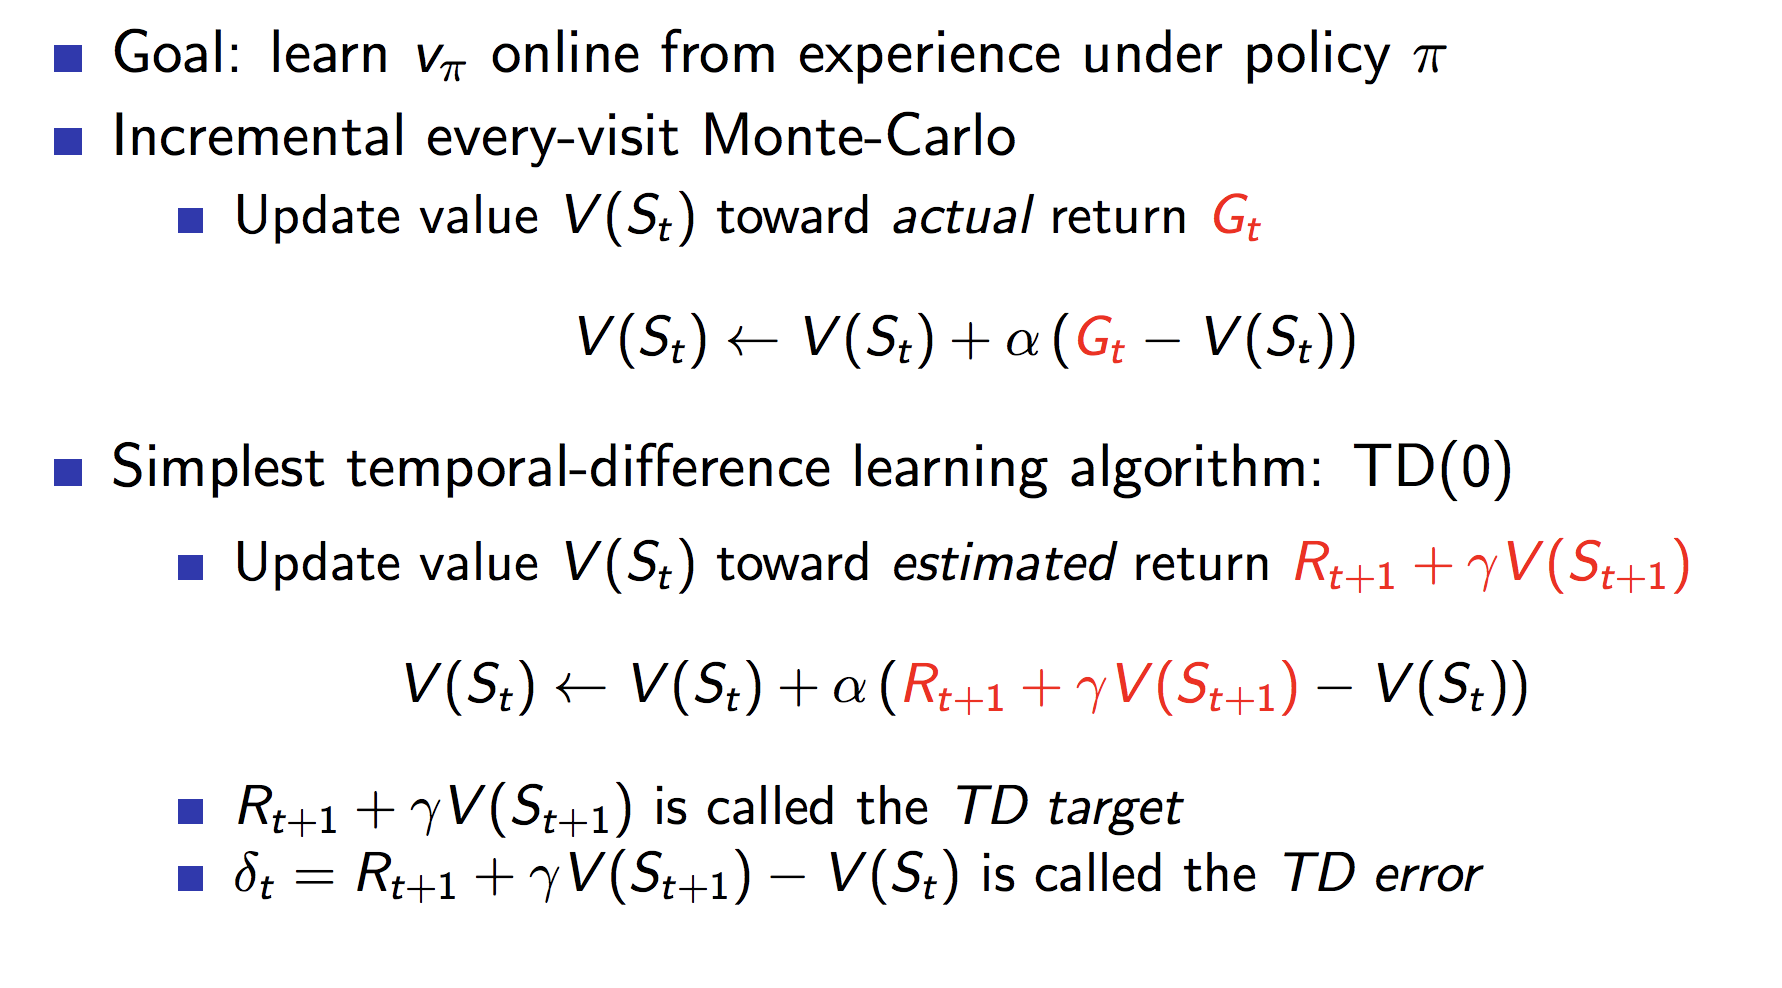
<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539684515624_Screen+Shot+2018-10-16+at+9.08.22+pm.png" alt=""><figcaption><p>difference between the value we got(TD target) after we took a step and what we had estimated perviously (difference of estimate before and after taking a step is the TD error)</p></figcaption></figure>

<br>

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539684906219_Screen+Shot+2018-10-16+at+9.14.55+pm.png" alt=""><figcaption></figcaption></figure>

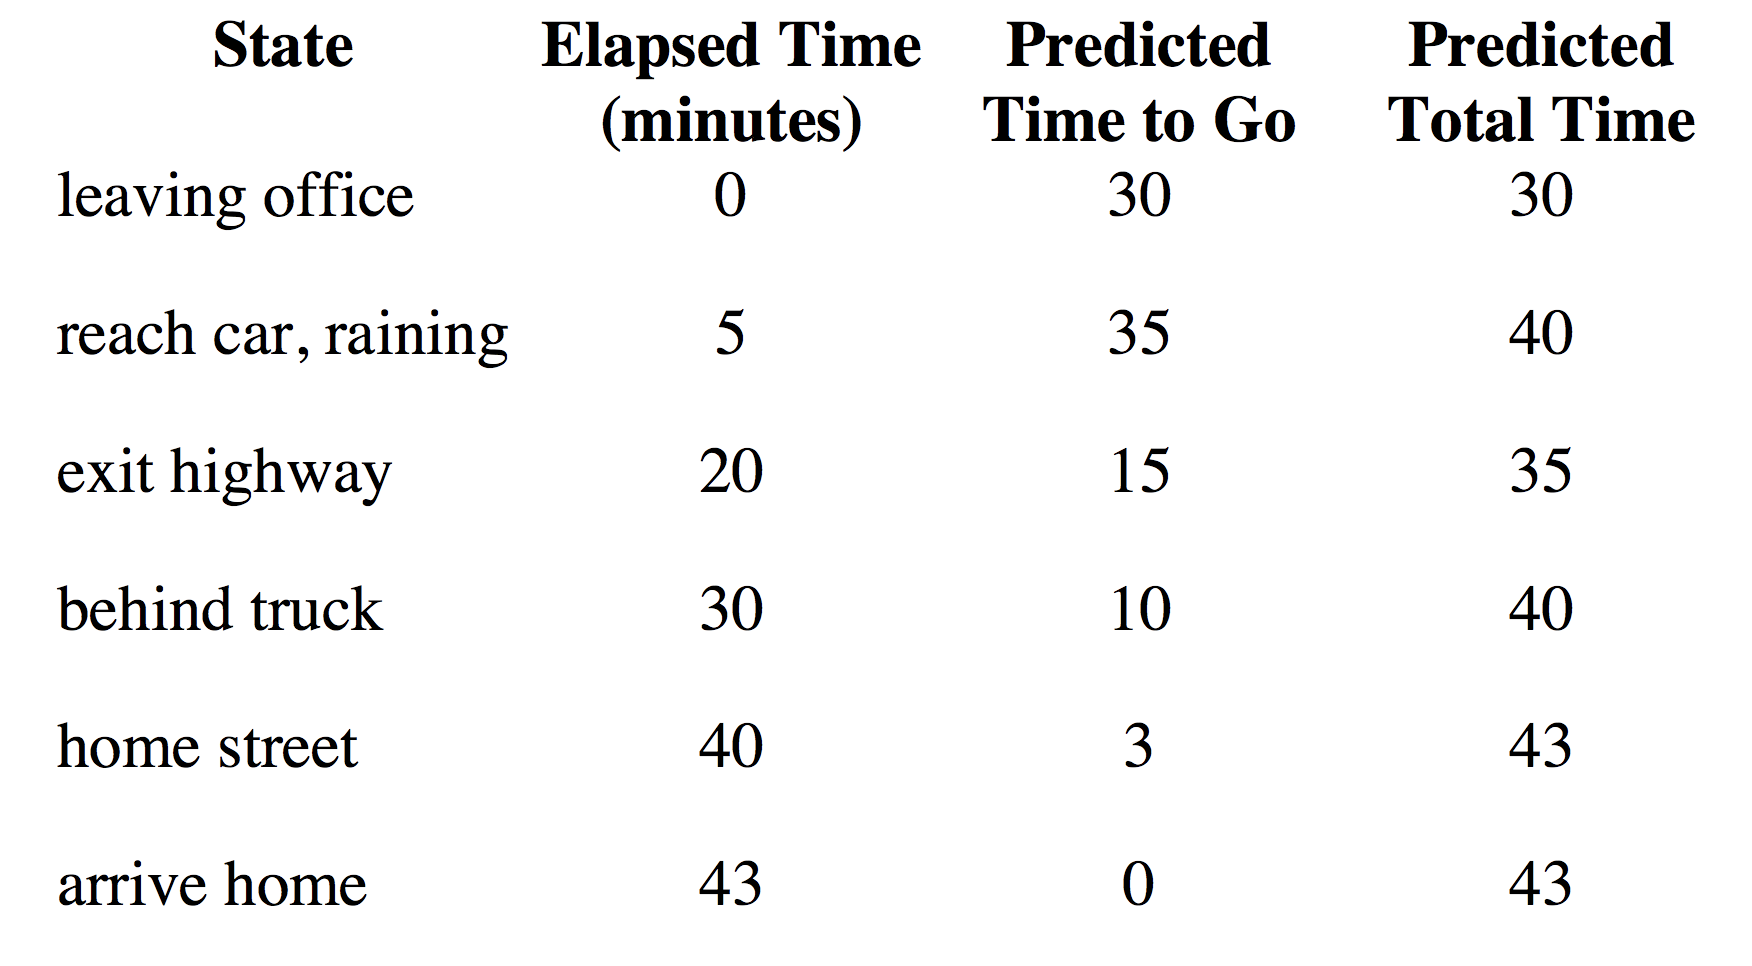
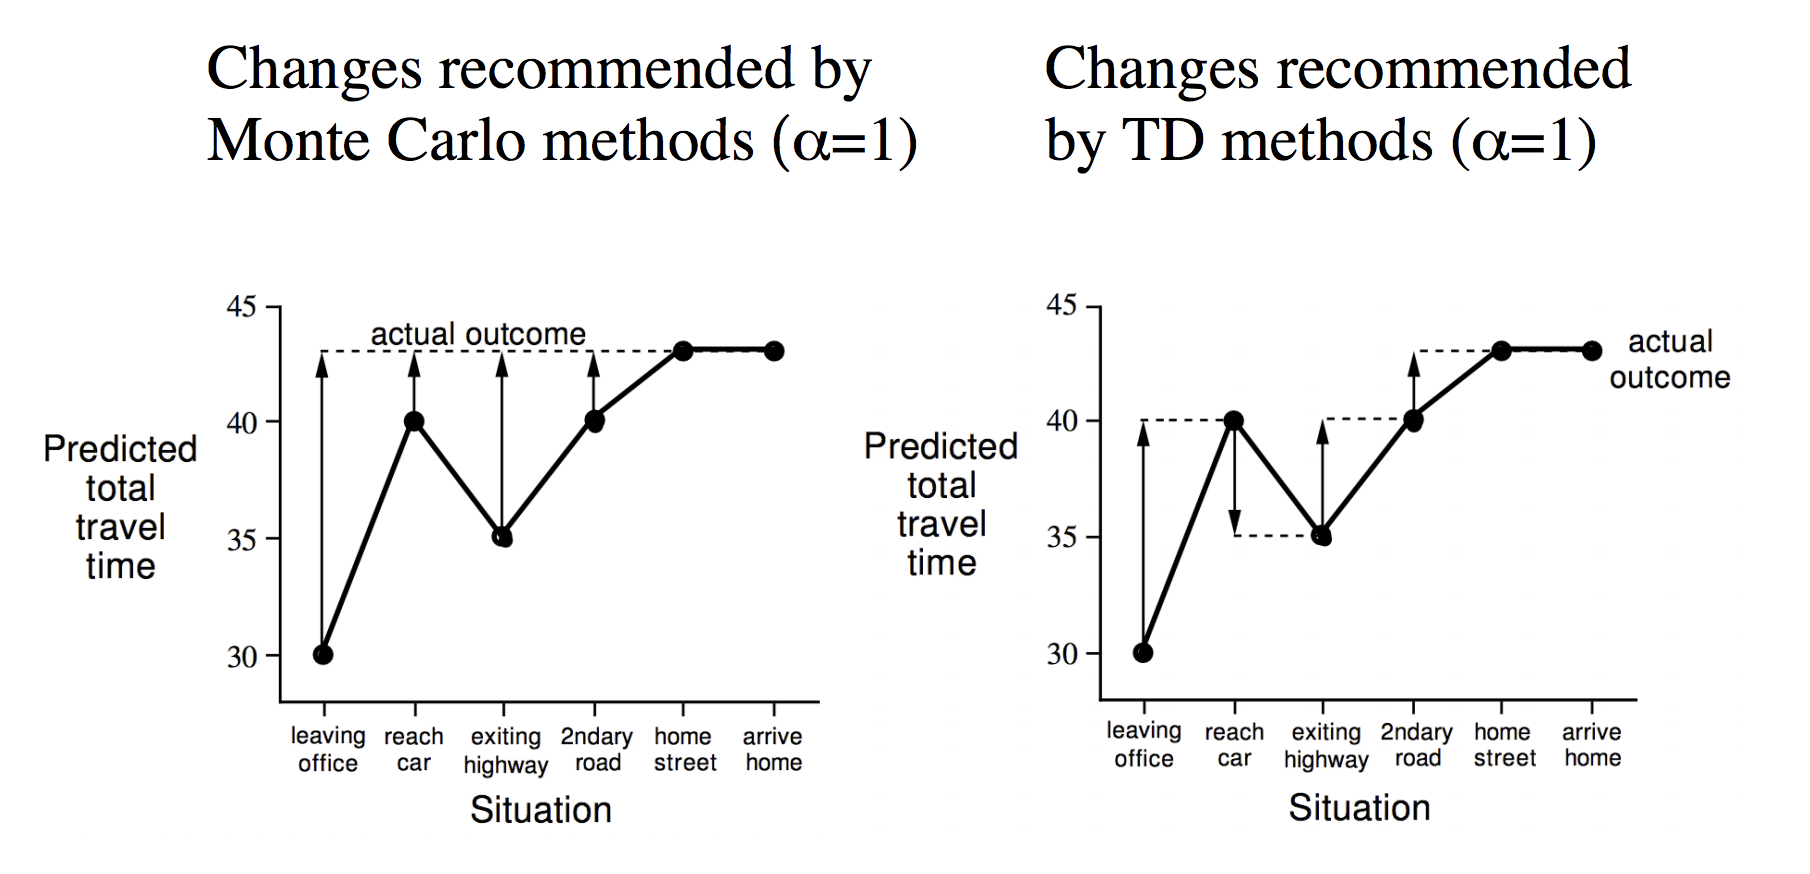
<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539685009735_Screen+Shot+2018-10-16+at+9.16.38+pm.png" alt=""><figcaption><p>In Monte Carlo we have to wait till the end to do the updates whereas in TD we can do it at each step</p></figcaption></figure>

<br>

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_C2839DD7CE43A3092B8673B66AAD690BD1244E255B173422EFDA55AD768D339E_1539685407941_Screen+Shot+2018-10-16+at+9.23.17+pm.png" alt=""><figcaption></figcaption></figure>

<br>

<figure><img src="https://paper-attachments.dropboxusercontent.com/s_49C2816153DB8034CC874B9D440F91A11F6D0190D3D2281A324055B40355999C_1538449351877_Screen+Shot+2018-10-02+at+1.02.19+pm.png" alt=""><figcaption></figcaption></figure>

TD(λ) algorithm:&#x20;